A2 - Clustering
Description
Section titled “Description”- In this assignment, you shall implement clustering on the blogs dataset containing 99 blogs.
- You can use any programming language you like.
- You shall present your application and code at an oral examination.
Submission instructions
Section titled “Submission instructions”See the Deadlines and Submissions page.
Requirements
Section titled “Requirements”| Grade | Requirements |
|---|---|
| E |
|
| C-D |
|
| A-B |
|
Test cases
Section titled “Test cases”K-means
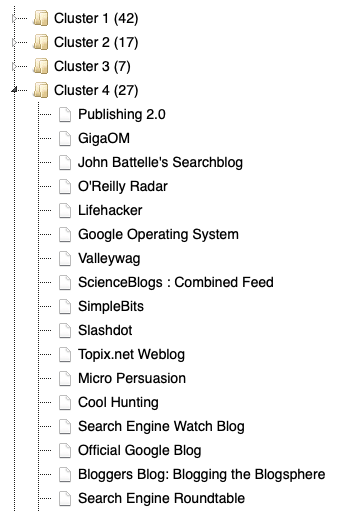
Section titled “K-means”K-means is not deterministic (the results differ between runs), but you usually find related blogs such as the Google and search engine blogs in one cluster as shown here:
Hierarchical
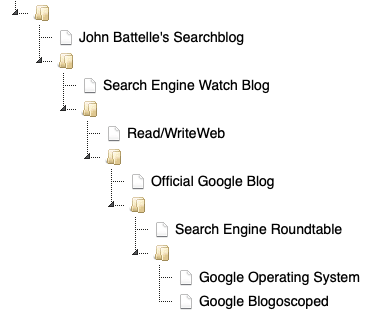
Section titled “Hierarchical”Hierarchical clustering always gives the same result. The tree is too large to show here, but if you get the branch shown below, it most likely works correctly: